Learn a visual policy.
A deep RL agent processes pixel observations. The experiments instantiate this component with a Deep Q-Network (DQN).
KDD 2023
Affiliations at publication: Nanjing University · Polixir Technologies
Learn from pixels.
Reason with rules.
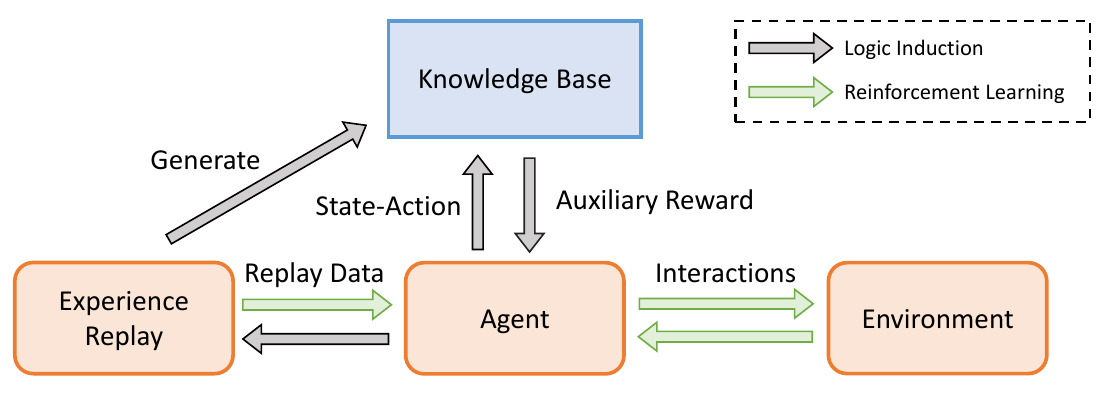
ILI turns symbolic experience into propositional knowledge,
then uses that knowledge to guide a visual reinforcement learning agent.
01 / The method
Pixels provide rich perceptual information. Symbols expose compact, meaningful features. ILI connects the two through reward shaping.
A deep RL agent processes pixel observations. The experiments instantiate this component with a Deep Q-Network (DQN).
RIPPER induces propositional rules from symbolic experience, capturing patterns from successful interactions.
An adaptive mechanism selects valuable knowledge and converts it into intrinsic rewards for the visual agent.
02 / The evidence
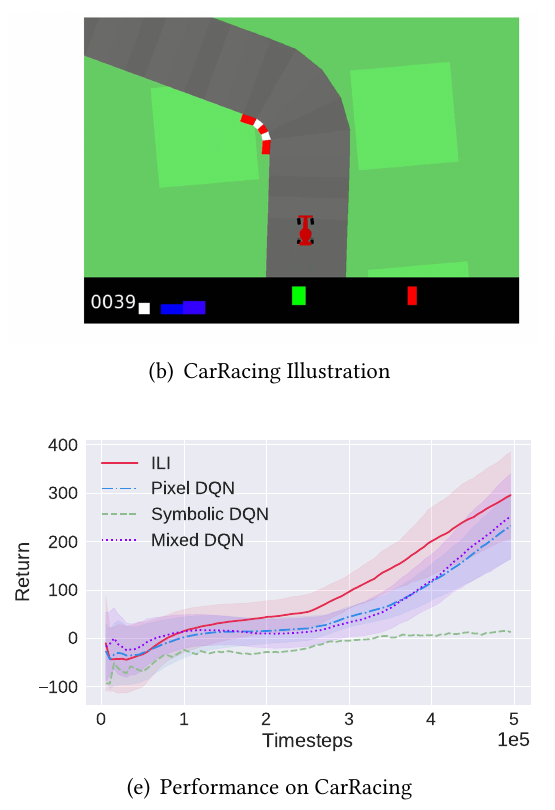
Experiments compare ILI with pixel-only, symbolic-only, and mixed-input DQN baselines.
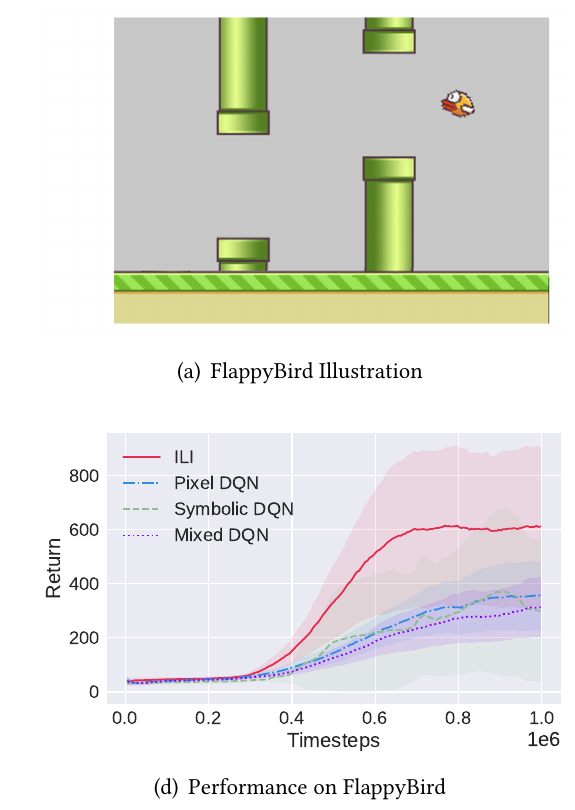
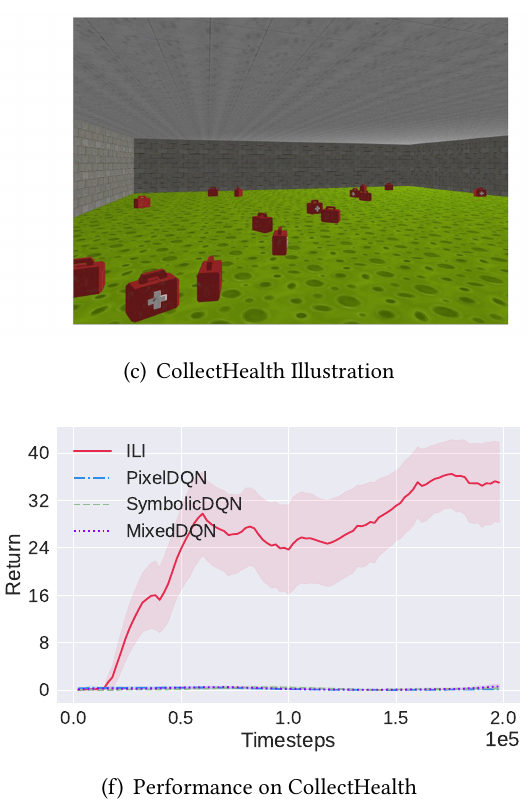
Symbolic distances provide task-relevant information that helps guide the visual policy.
The paper reports smaller improvements here: the symbolic state omits decision-relevant information such as speed and road corners.
Separate experiments change entity colors while keeping task logic intact. Induced symbolic knowledge helps learning in the new visual setting.
03 / Interpretation
ILI assumes that both pixel and symbolic observations are available. Its performance depends on the symbolic information and the quality of induced knowledge. The transfer experiments change visual semantics within the studied tasks; they do not establish general transfer to arbitrary environments.
In the authors’ words
Reinforcement Learning (RL) has experienced rapid advancements in recent years. The widely studied RL algorithms mainly focus on a single input form, such as pixel-based image input or symbolic vector input. These two forms have different characteristics and, in many scenarios, will appear together, while few RL algorithms have studied the problems with mixed input types. Specifically, in the scenario where both pixel and symbolic inputs are available, symbolic input usually offers abstract features with specific semantics, which is more conducive to the agent’s focus. Conversely, pixel input provides more comprehensive information, enabling the agent to make well-informed decisions. Tailoring the processing approach based on the properties of these two input types can contribute to solving the problem more effectively.
To tackle the above issue, we propose an Internal Logical Induction (ILI) framework that integrates deep RL and rule learning into one system. ILI utilizes the deep RL algorithm to process the pixel input and the rule learning algorithm to induce propositional logic knowledge from symbolic input. To efficiently combine these two mechanisms, we further adopt a reward shaping technique by treating valuable knowledge as intrinsic rewards for the RL procedure. Experimental results demonstrate that the ILI framework outperforms baseline approaches in RL problems with pixel-symbolic input, and its inductive knowledge exhibits transferability advantages when pixel input semantics change.
Explore the work
Build on this work
Jiacheng Xu, Chao Chen, Fuxiang Zhang, Lei Yuan, Zongzhang Zhang, and Yang Yu. “Internal Logical Induction for Pixel-Symbolic Reinforcement Learning.” KDD 2023, pages 2825–2837. DOI: 10.1145/3580305.3599393.
@inproceedings{xu2023internal,
  title     = {Internal Logical Induction for Pixel-Symbolic
               Reinforcement Learning},
  author    = {Jiacheng Xu and Chao Chen and Fuxiang Zhang and
               Lei Yuan and Zongzhang Zhang and Yang Yu},
  booktitle = {Proceedings of the 29th ACM SIGKDD Conference on
               Knowledge Discovery and Data Mining},
  pages     = {2825--2837},
  year      = {2023},
  doi       = {10.1145/3580305.3599393}
}Figures 4 and 6 from Jiacheng Xu et al., KDD 2023. Cropped from the conference paper; © 2023 the authors, publication rights licensed to ACM.